Separate weights, context and runtime memory
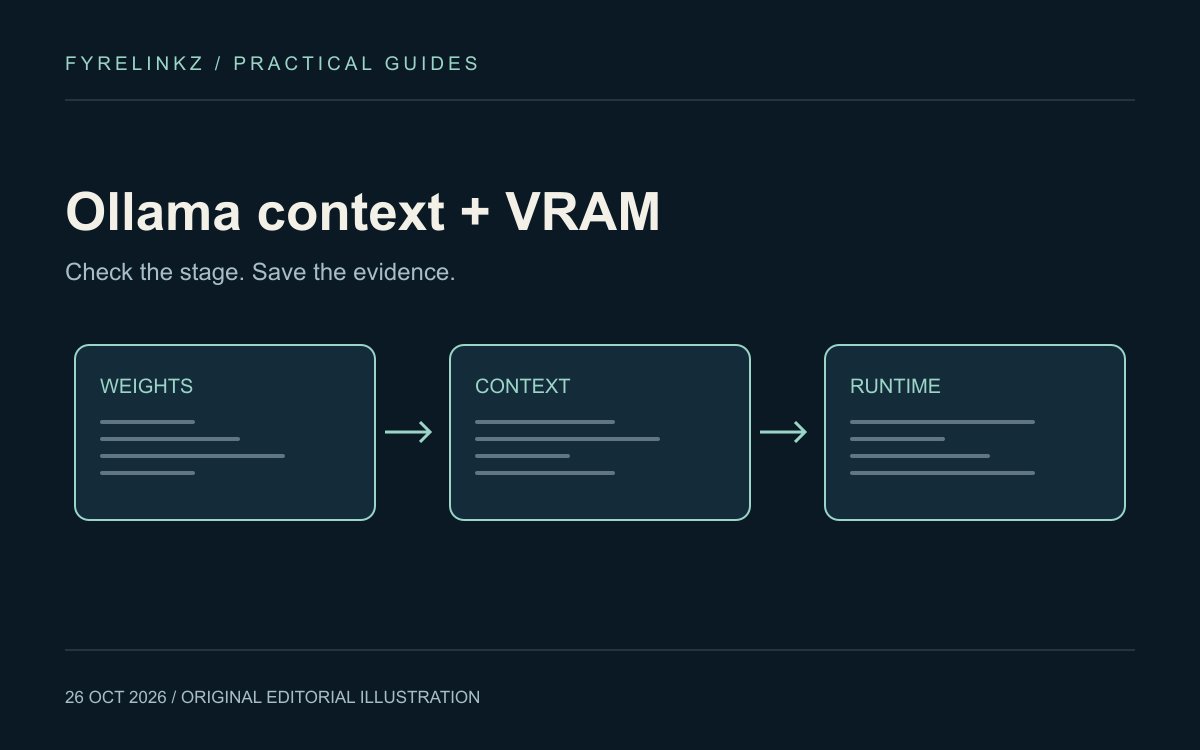
Model weights are only part of inference memory. The running process also allocates context/KV-cache and working buffers. Display use and other applications affect available GPU memory. File size is not a peak-VRAM measurement.
Compare quantizations on your own task
llama.cpp provides model quantization tools and formats. Compatibility and quality depend on the exact model and runtime. Keep the prompt, context and evaluation rules fixed when comparing artifacts. Do not transfer a perplexity result from another model to your own workload.
Treat context and offloading as separate controls
Start with the context your application needs. Check your runtime's current help before changing cache formats or GPU-layer allocation: flags and support differ. CPU/GPU offloading can change memory use and latency; measure both rather than assuming a fixed penalty.
Record a reproducible result
Save the model digest, runtime version, driver, context, prompt and allocation. Run the same task more than once, distinguish cold and warm starts, and retain rejected answers. Use the laptop guide and blank run log for a recording template.
| Change | Record | Accept only if |
|---|---|---|
| Weight quantization | Exact artifact and output quality | Required answers remain useful |
| Context limit | Allocated context and task length | Required inputs still fit |
| CPU/GPU allocation | Memory, completion time and allocation | Turnaround remains acceptable |
Frequently asked questions
Does a 4-bit model always preserve the original model's quality?
No. Quantization changes numerical precision and can affect output quality. Evaluate the exact model, quantization and task; there is no universal quality-retention percentage.
Why can a model download fit on disk but exceed GPU memory?
Inference also needs context/KV-cache allocations and runtime buffers. Other applications use memory too. Measure the complete running workload rather than treating file size as peak VRAM.
Sources & further reading
Primary sources checked Oct 17, 2026. Vendor statements are attributed; editorial advice is our own.
- 1Model quantization tooling ↗llama.cpp
Help us keep this useful. Report a factual correction →